DHI Seed Fund · Fall 2025 · to be launched in Spring 2026
Manchu OCR and Translation AI
A system that reads and segments Manchu script from real historical sources, built on a fine-tuned vision-language model, and heading towards transliteration and machine translation.
what the project does
Automatically reading a script that no ready-made tool reads.
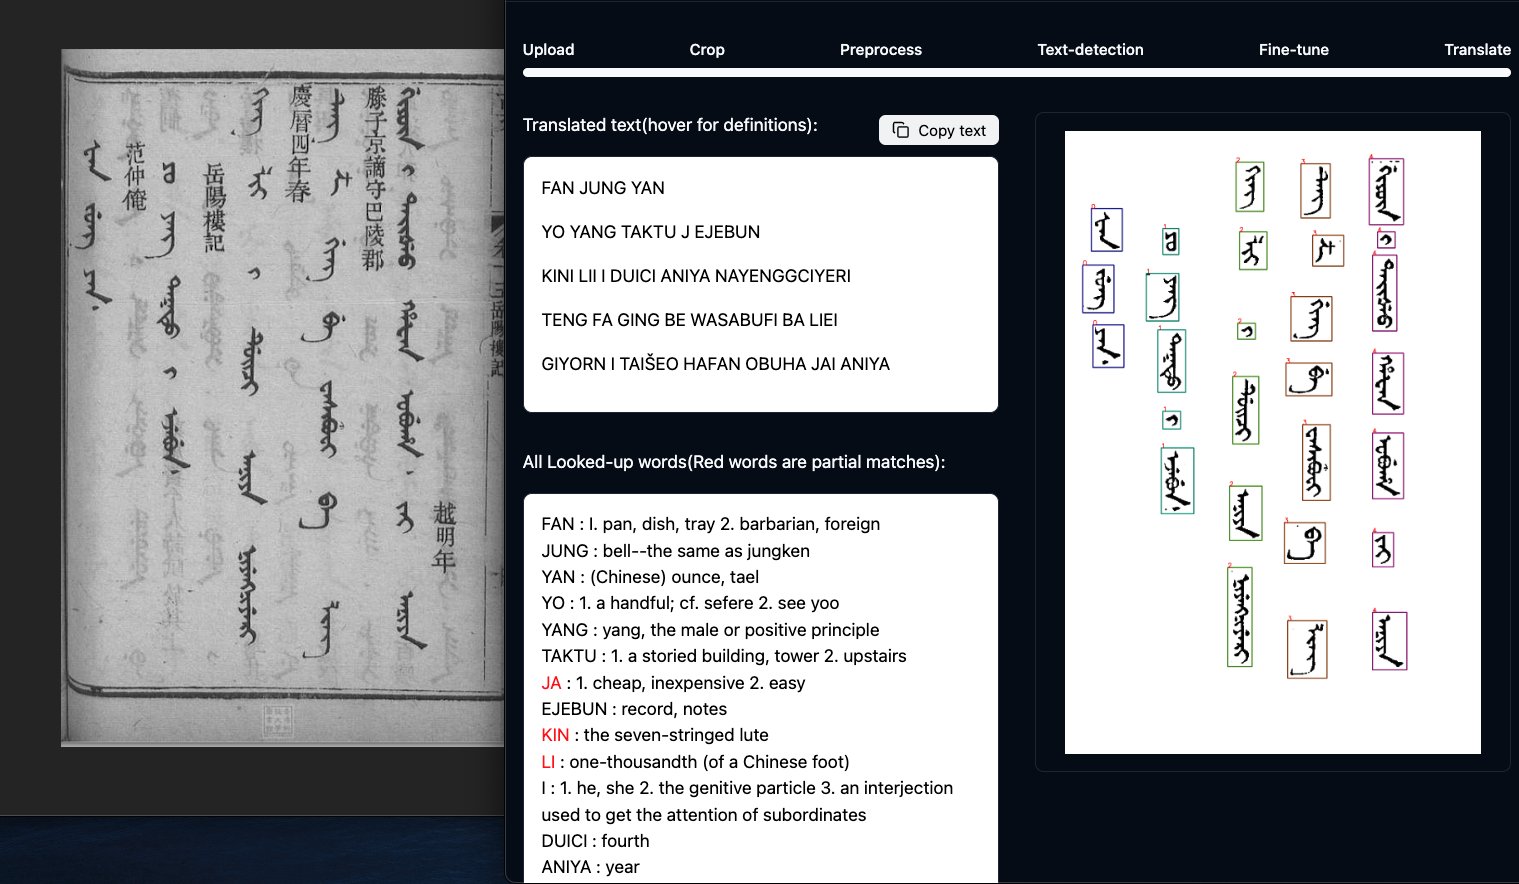
The project is building a reliable, high-accuracy system capable of reading and segmenting Manchu script from real historical sources. It rests on a custom word-segmentation workflow and a large corpus of synthetic and real-world scans collected from several repositories.
That work has already produced a fine-tuned vision-language model that performs strongly on real scanned material. Early tests show it recognising printed and well-written archival pages, which is what makes modern OCR plausible for a low-resource script with complex vertical structures and variable calligraphic styles.
where it stands
-
built
A fine-tuned vision-language model
Trained on synthetic and real scans, with a custom word-segmentation workflow in front of it. It reads printed and well-written archival pages.
-
next
More data, then the pipelines
Expanding the training corpus and strengthening performance, then connecting the OCR output to transliteration and machine translation.
-
outcome
Archives as searchable text
A practical tool that turns Manchu archival documents into searchable, analyzable text, and a transferable framework for OCR in other endangered or low-resource languages.
the team
- Principal investigator
- Prof. Michael CHUNG, Division of Humanities
- Research assistant
- Hanlin WANG, student of Information Technology, Department of Computer Science and Engineering
- Project support
- Dr. Steve MA, Division of HumanitiesYifan WANG, Library