Fall 2025 · HUMA5630 · named entity recognition
The Application of NER Models in the Literature Field
Three models, one Chinese novel. This project teaches a machine to mark people, places and works in modern literature, and asks what it can see that a reader only feels.
one line, four kinds of entity
在上海LOC,淮海路LOC與國泰戲院LOC之間,金宇澄PER寫下《繁花》WORK。
Between Huaihai Road and the Cathay Cinema in Shanghai, Jin Yucheng wrote Blossoms.
- PERperson
- LOCplace
- ORGorganisation
- WORKwork
three models, one training set
| model | accuracy | token level | entity level | ||||
|---|---|---|---|---|---|---|---|
| P | R | F1 | P | R | F1 | ||
| CRF | 0.8526 | 0.5619 | 0.4883 | 0.5156 | 0.6926 | 0.6049 | 0.6458 |
| BERT-Tiny | 0.8698 | 0.5648 | 0.5248 | 0.5420 | 0.6037 | 0.6370 | 0.6199 |
| BERT-Base | 0.8939 | 0.6299 | 0.6024 | 0.6011 | 0.6908 | 0.7242 | 0.7071 |
One training set for all three: about 4,800 sentences, roughly a million lines. Token level scores every word; entity level scores whole entities. Accuracy is shared, so it is shown once.
Digital Humanities Student Project (Fall 2025). This project is a course project for HUMA5630 Digital Humanities.
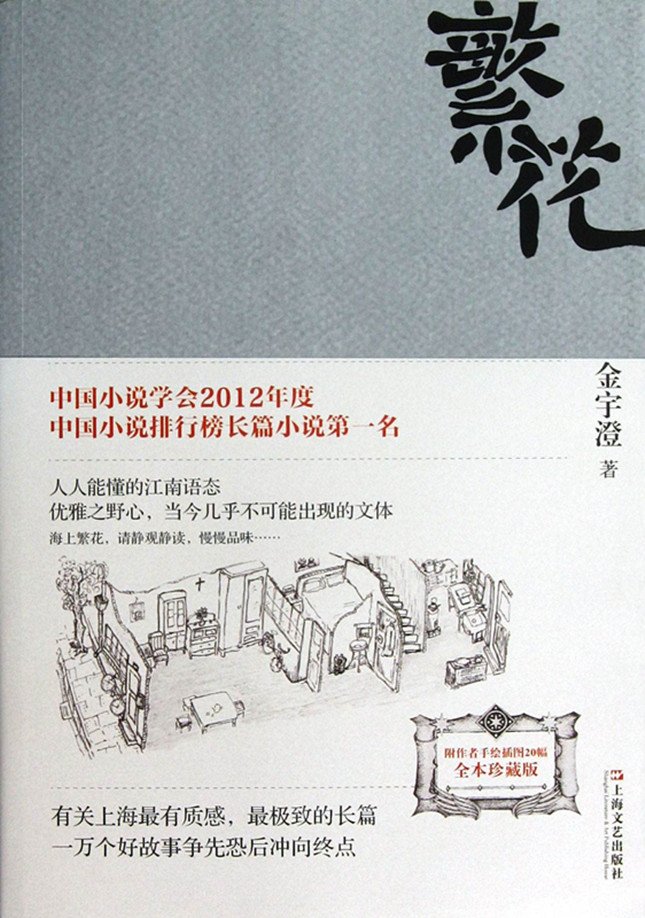
Book cover of Blossoms by Jin Yucheng
01About This Project
- Our project aims to build a NER model for modern and contemporary Chinese literature, exploring the value of NER in assisting literary research.
- Given a Chinese text as input, the expectation is for the model to scan each word in the text and identify the entities within it (such as people, places, concepts, times, etc.). This is an entity recognition (NER) task.
02Possible Uses: Geocriticism
- A method of spatial criticism for literary texts.
- An interdisciplinary product combining Chinese literature and geography studies.
- We can use NER to assist in identifying geographical names in literature, thereby constructing the geographical space of a specific literature and understanding the literary memories of that place.
03CRF Model
- The full name of CRF is Conditional Random Fields (CRF), a probabilistic graphical model used for tagging and segmenting sequential data. It belongs to a discriminative model, meaning it directly models the conditional probability of the output tagging sequence given the input sequence, without modeling the overall distribution of the input.
- In simple terms, CRF assigns the most reasonable label to each position by considering the dependency between consecutive labels.
04BERT Model
BERT-Tiny
- Using the open-source model at https://huggingface.co/ckiplab/bert-tiny-chinese-ner, this model is fine-tuned from BERT-Tiny Chinese by CKIP Lab and supports Traditional Chinese.
- Basic information of the BERT model: 12M parameters, 4 layers, hidden layer dimension size of 312;
- Additional classification layer: 312 dimensions → 73 dimensions, classifying tokens into 73 entity labels.
BERT-Base
- Using the open-source model at https://huggingface.co/ckiplab/bert-base-chinese-ner, which was fine-tuned by CKIP Lab based on BERT Base Chinese and supports Traditional Chinese.
- Basic information of the BERT model: 110M parameters, 12 layers, hidden layer dimension size of 768;
- Additional classification layer: 768 dimensions → 73 dimensions, classifying tokens into 73 entity labels.
- CRF Model — training time consumption: 15 min; inference speed (token/s): about 9407
- BERT-Tiny — training time consumption: 15 min; inference speed (token/s): about 14940
- BERT-Base — training time consumption: about 1 h; inference speed (token/s): about 3715
05Result Comparing
- Training environment for the CRF model (using CPU): Intel(R) Core(TM) i5-9300H CPU @ 2.40GHz (8G)
- Fine-tuning environment for the bert-tiny and bert-base models (using GPU): NVIDIA GeForce RTX 4090 (24G)
- Number of training sets: approximately 4800 sentences, totalling 1 million lines
06Token
- CRF — Accuracy 0.8526; Precision 0.5619; Recall 0.4883; F1-Score 0.5156
- bert-tiny — Accuracy 0.8698; Precision 0.5648; Recall 0.5248; F1-Score 0.5420
- bert-base — Accuracy 0.8939; Precision 0.6299; Recall 0.6024; F1-Score 0.6011
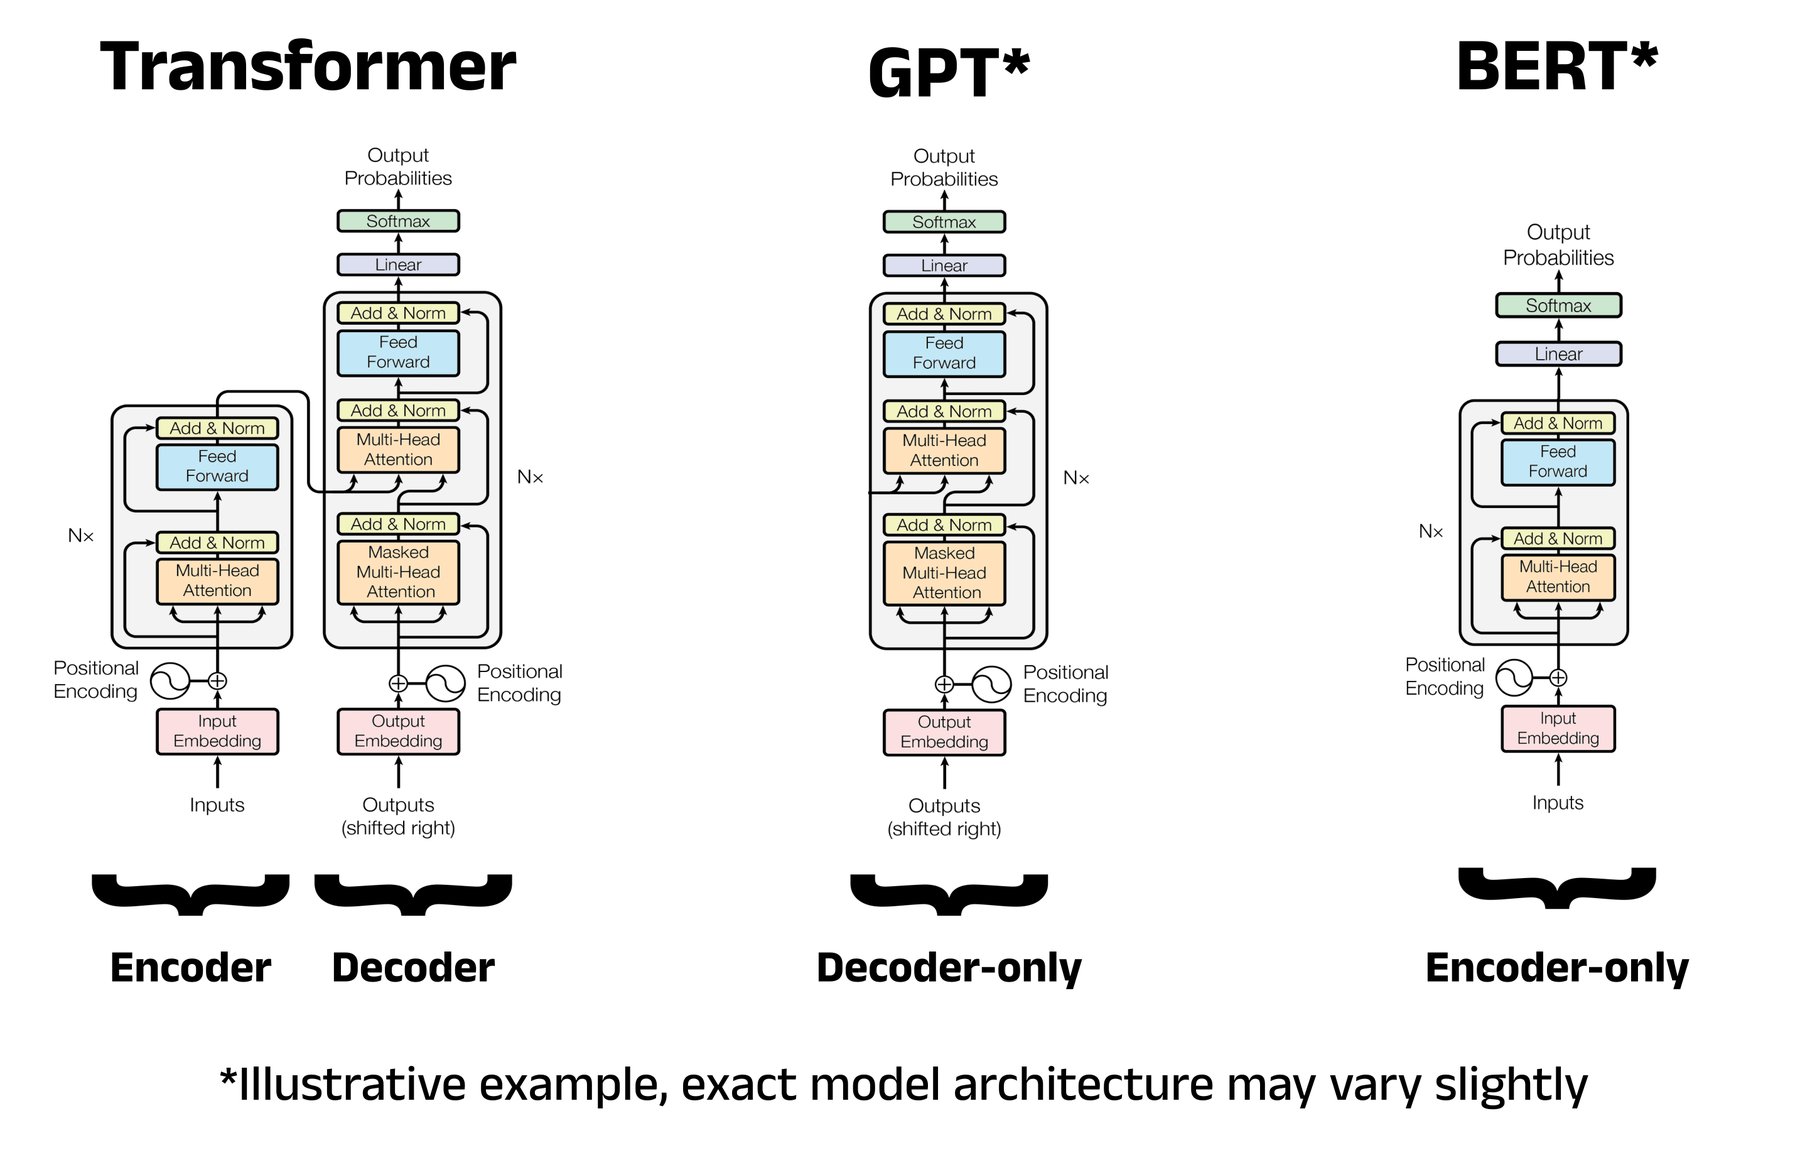
A comparison of the architectures for the Transformer, GPT, and BERT. Image adapted by author from the Transformer architecture diagram in the “Attention is All You Need” paper
07Entity
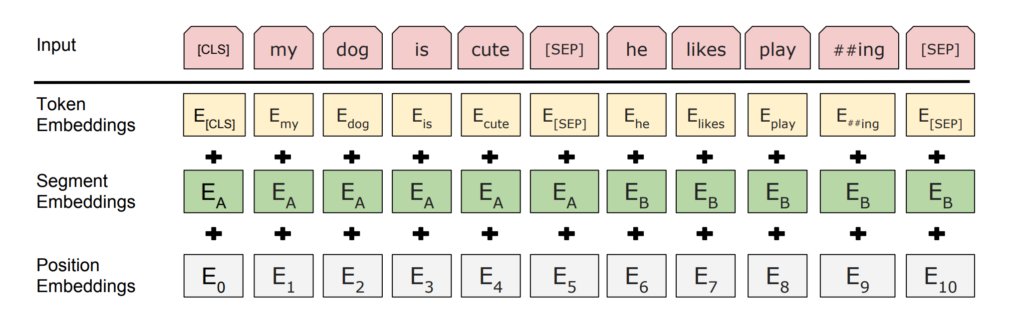
An overview of the BERT embedding process. Image taken from the BERT paper
- CRF — Accuracy 0.8526; Precision 0.6926; Recall 0.6049; F1-Score 0.6458
- bert-tiny — Accuracy 0.8698; Precision 0.6037; Recall 0.6370; F1-Score 0.6199
- bert-base — Accuracy 0.8939; Precision 0.6908; Recall 0.7242; F1-Score 0.7071
Practical Uses
By using NER, we can make the construction of geographical space in literature more precise and systematic.
For example, we can achieve automatic extraction of entities: quickly identify place names such as lan, Cao Yang New Village and Suzhou River in the text, avoiding omissions in manual annotation.
We can also construct a spatial relationship network: by identifying the co-occurrence relationships of place names (such as the frequent co-occurrence of Huaihai Road and Guo Tai Cinema), we can reveal the spatial differentiation between Shang Zigu (Luwan District) and Xia Zigu (Huaxi District) in Shanghai, assisting in the hierarchical spatial analysis in the geography and literature dimension.
By analysing the frequently occurring place names in the literature of a certain region (such as Jiuzhou and Xiguan in Guangzhou, and Teahouse and Jinli in Chengdu), the literary landmarks of that city can be extracted, providing materials for the construction of local cultural brands (such as using Biancheng as the literary IP of Xiangxi’s tourism and culture).
Specific examples: Yan Food Diary and Like a Seal and a Jade were both published in recent years. Both focus on the urban literature of Lingnan. Through NER entity recognition, it was found that both, in writing about Lingnan, repeatedly used the same place names, such as Jiuzhou, which appears in both of their literary works.
08Student
- WU Wen-shin — MA Chinese Culture
- LIANG Xiaojing — MA Chinese Culture
- LI Jialu — MA Social Science
- TSOI Sin Yu — MA Chinese Culture
09GitHub Repository
Please find the detailed code and project documentation at the link below.
place names the model pulled out of the literature
- 九洲
- 西關
- 茶館
- 錦里
- 邊城
- 蘇州河
- 曹楊新村
- 淮海路
- 國泰戲院
- 弄
Place names the model recognised across the novels, the raw material for mapping the geography a text remembers.
what it found
九洲 surfaces in both novels. Two books about Lingnan, and the same place names keep coming back: that repetition is exactly what a reader misses and a tagger finds.
practical uses · geocriticism