Prof. YANG Zekun, Assistant Professor, Department of Information and Computer Technology, Tokyo University of Science
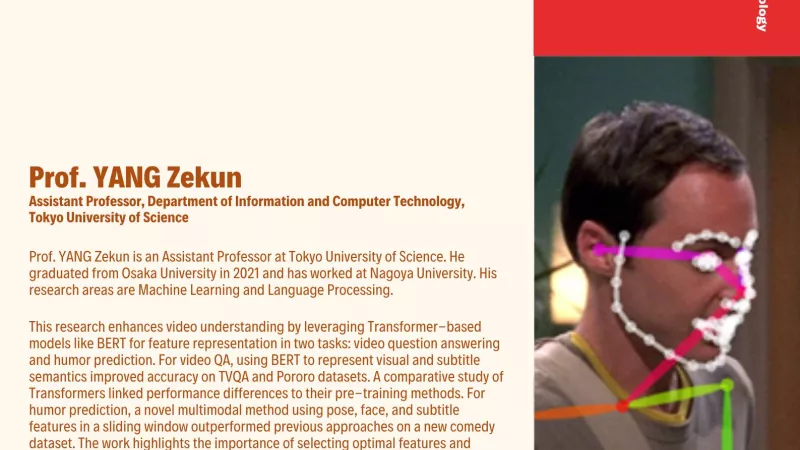
This research enhances video understanding by leveraging Transformer-based models like BERT for feature representation in two tasks: video question answering and humor prediction. For video QA, using BERT to represent visual and subtitle semantics improved accuracy on TVQA and Pororo datasets. A comparative study of Transformers linked performance differences to their pre-training methods. For humor prediction, a novel multimodal method using pose, face, and subtitle features in a sliding window outperformed previous approaches on a new comedy dataset. The work highlights the importance of selecting optimal features and models for deeper video analysis.